Evidence before promises
Built, Tested, and Still Being Proven.
Kinode has demonstrated segmented Qwen3-8B inference across physical Apple Silicon and NVIDIA CUDA devices. Implementation alone is not treated as acceptance.
| Capability | Status |
|---|---|
| Heterogeneous segmented inference using Apple Silicon and NVIDIA CUDA | StatusDemonstrated |
| Physical execution of Qwen3-8B in a laboratory topology | StatusDemonstrated |
| Capability-aware resource planning | StatusImplemented, qualification ongoing |
| Resource admission | StatusImplemented, qualification ongoing |
| Owner commitments | StatusImplemented, qualification ongoing |
| Leases and resource protection | StatusImplemented, qualification ongoing |
| Oversized-model Capacity Unlock | StatusIn progress, physical proof pending |
| Sustained performance benchmarking | StatusIn progress, physical proof pending |
| Reliability qualification | StatusIn progress, physical proof pending |
| Controlled beta user experience | StatusIn progress, physical proof pending |
| Managed inference API platform | StatusFuture direction |
| Permissioned compute supply network | StatusFuture direction |
| Commercial marketplace and billing | StatusFuture direction |
Read the technical boundaries
The demonstrated path partitions Qwen3-8B Q4_K_M between a Mac-based coordinator and an NVIDIA CUDA worker. It establishes real remote participation in a bounded laboratory configuration.
This is not a production-readiness or performance-advantage claim. Timing boundaries differ across existing measurements, so the figures below are not a performance comparison. Repeatable oversized-model execution, broader compatibility and reliability remain qualification milestones.
| Run | Decode | Context |
|---|---|---|
| Distributed path, headline | ~1.23 tokens/s | Mac coordinator and remote GTX 1050 CUDA worker. 5 input and 2 output tokens, 3 repetitions, product-level timing. |
| Distributed path, separate timing view | ~0.955 tokens/s | A distinct timing boundary, not interchangeable with the headline. |
| Single M2 Pro, local | ~23.37 tokens/s | Same model family, separate setup and timing conditions. |
These are short laboratory observations, not a like-for-like sustained benchmark. The arithmetic ratio of about 19 is illustrative only, and neither a speedup claim nor proof of capacity beyond the best individual node follows. Distribution is not presented as a performance win today. The reason to pursue it is capacity.
The experience taking shape
A clear view of your compute.
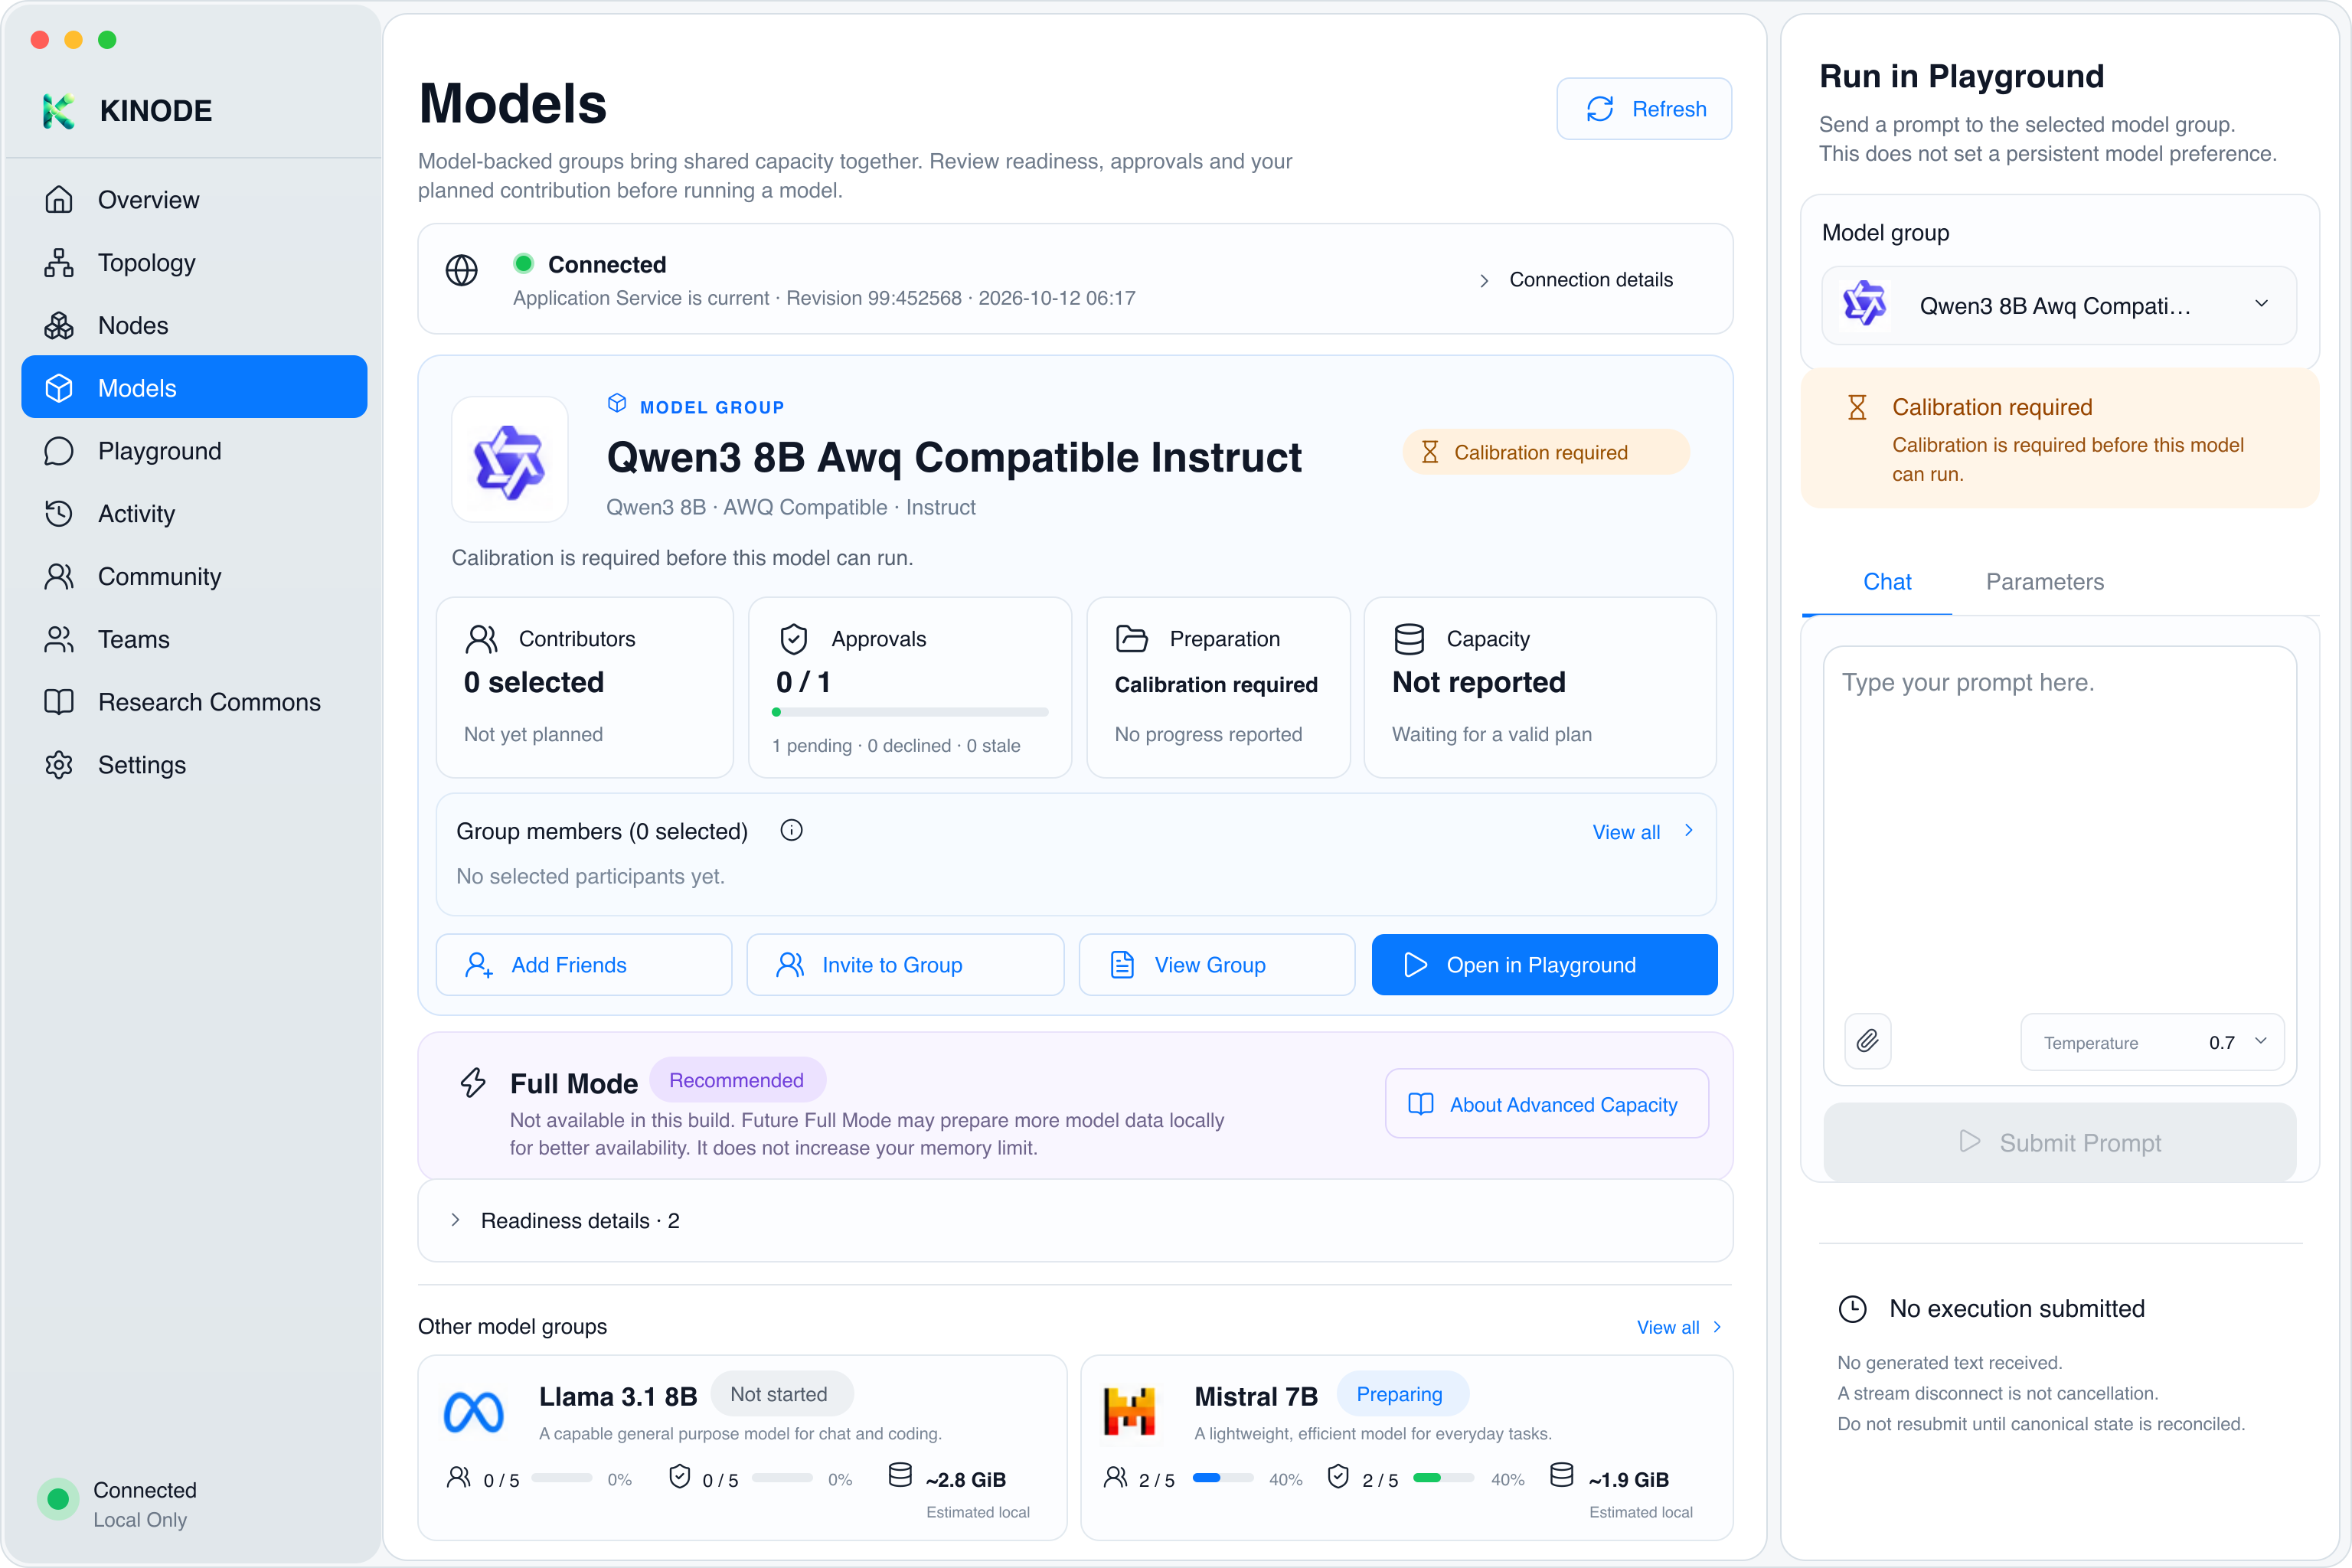
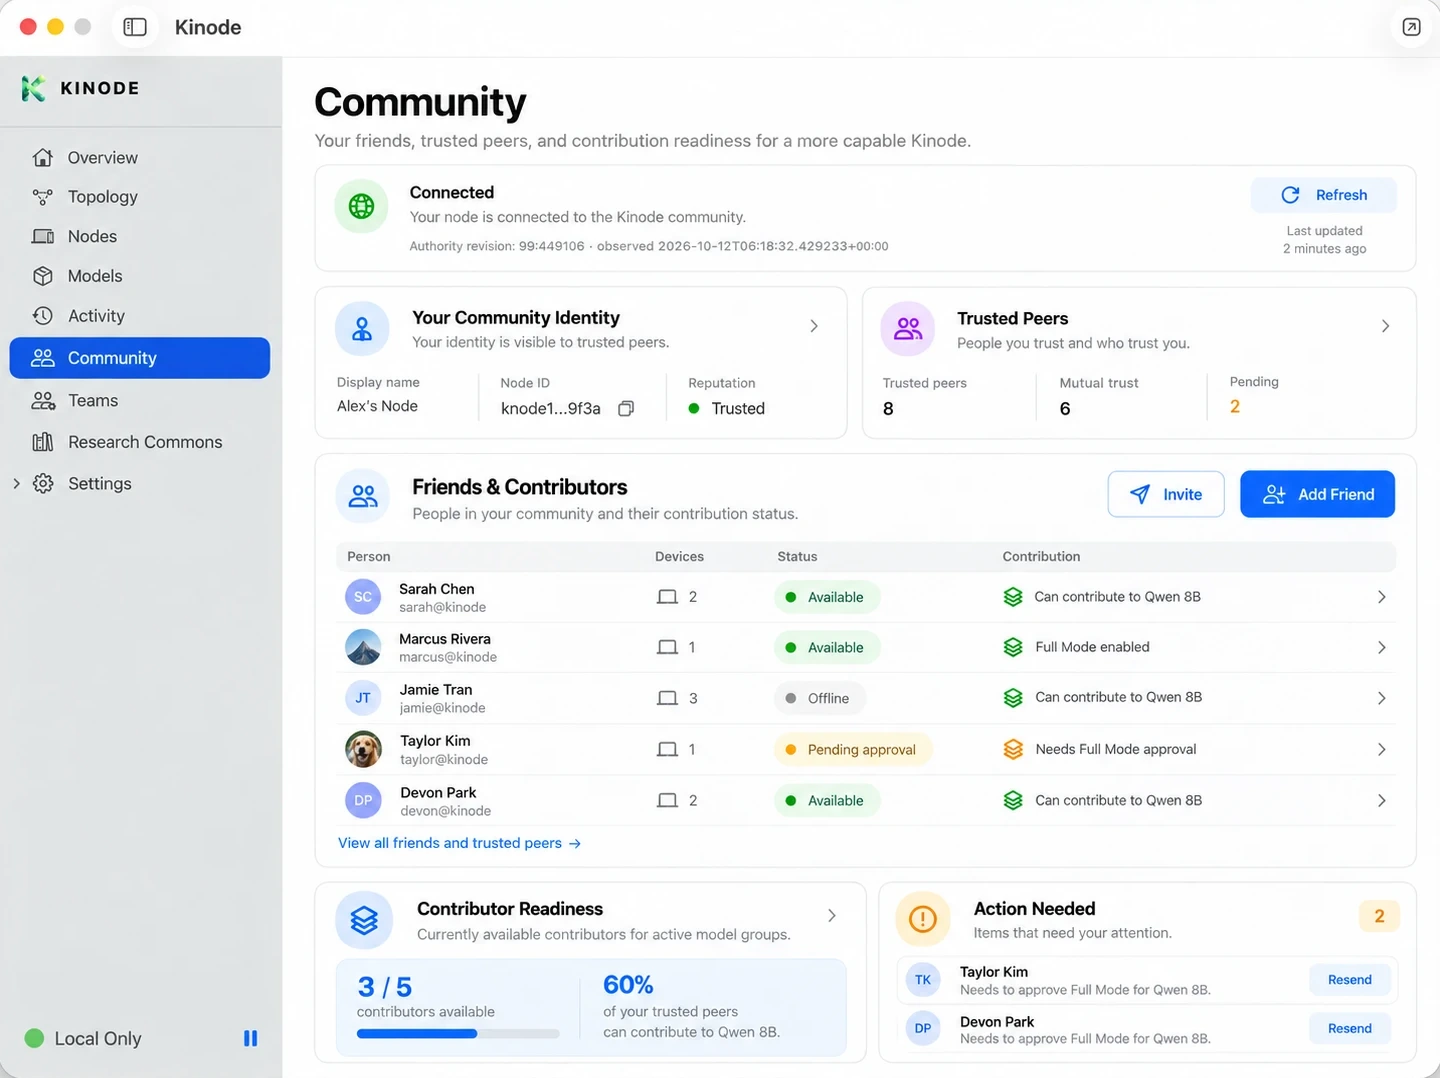
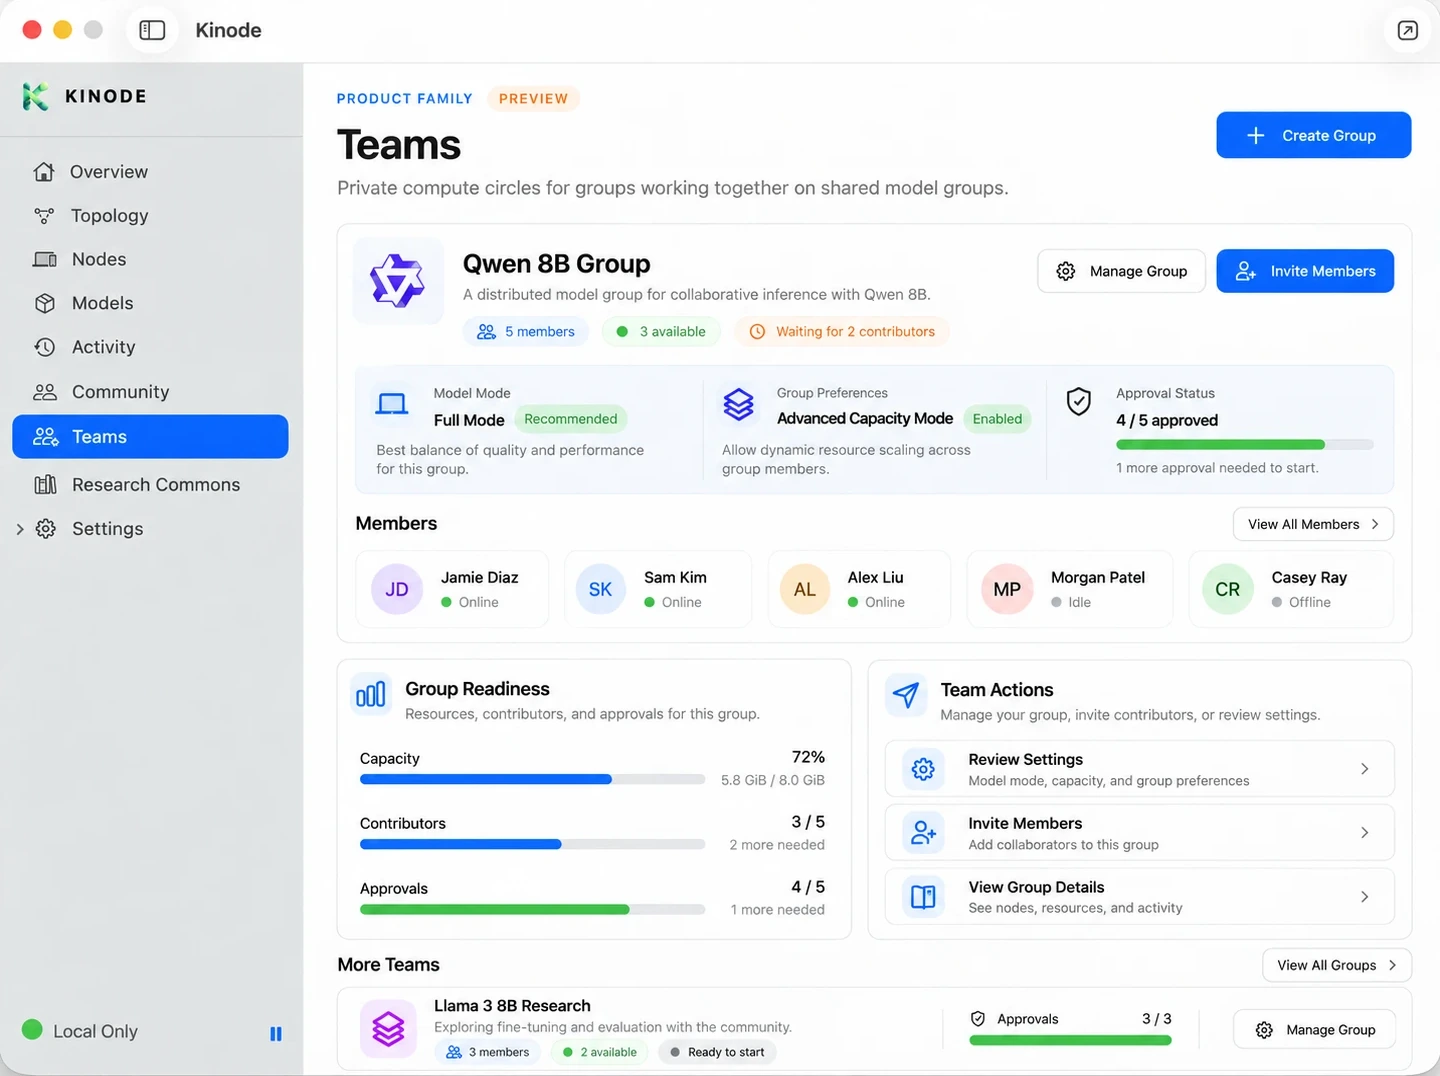
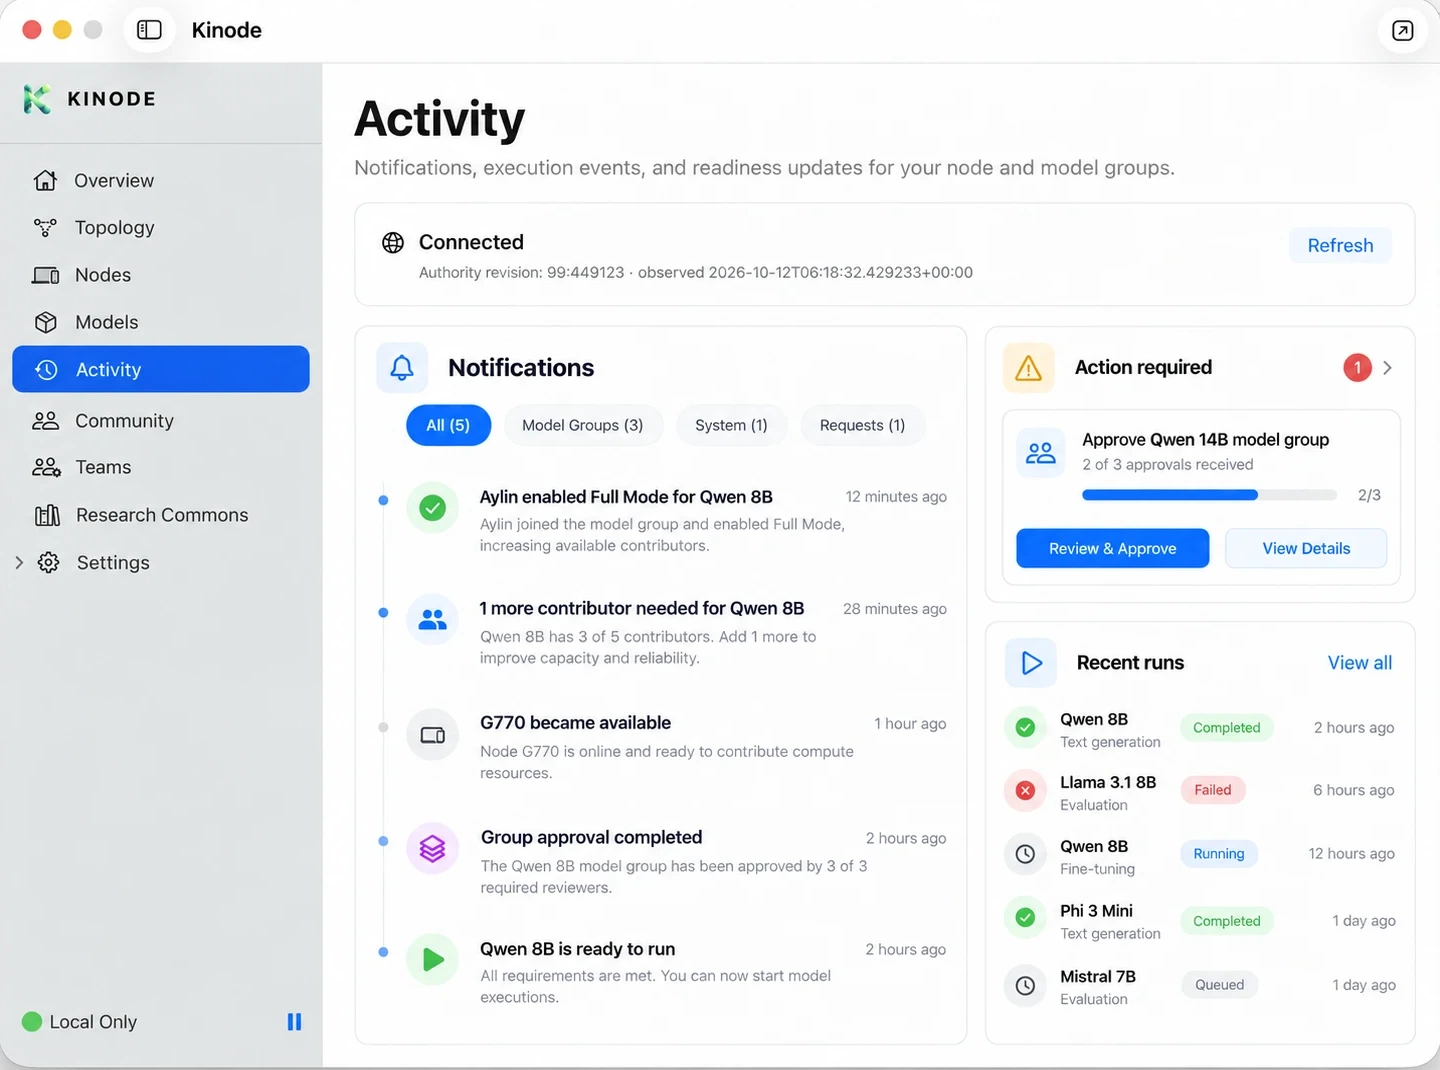
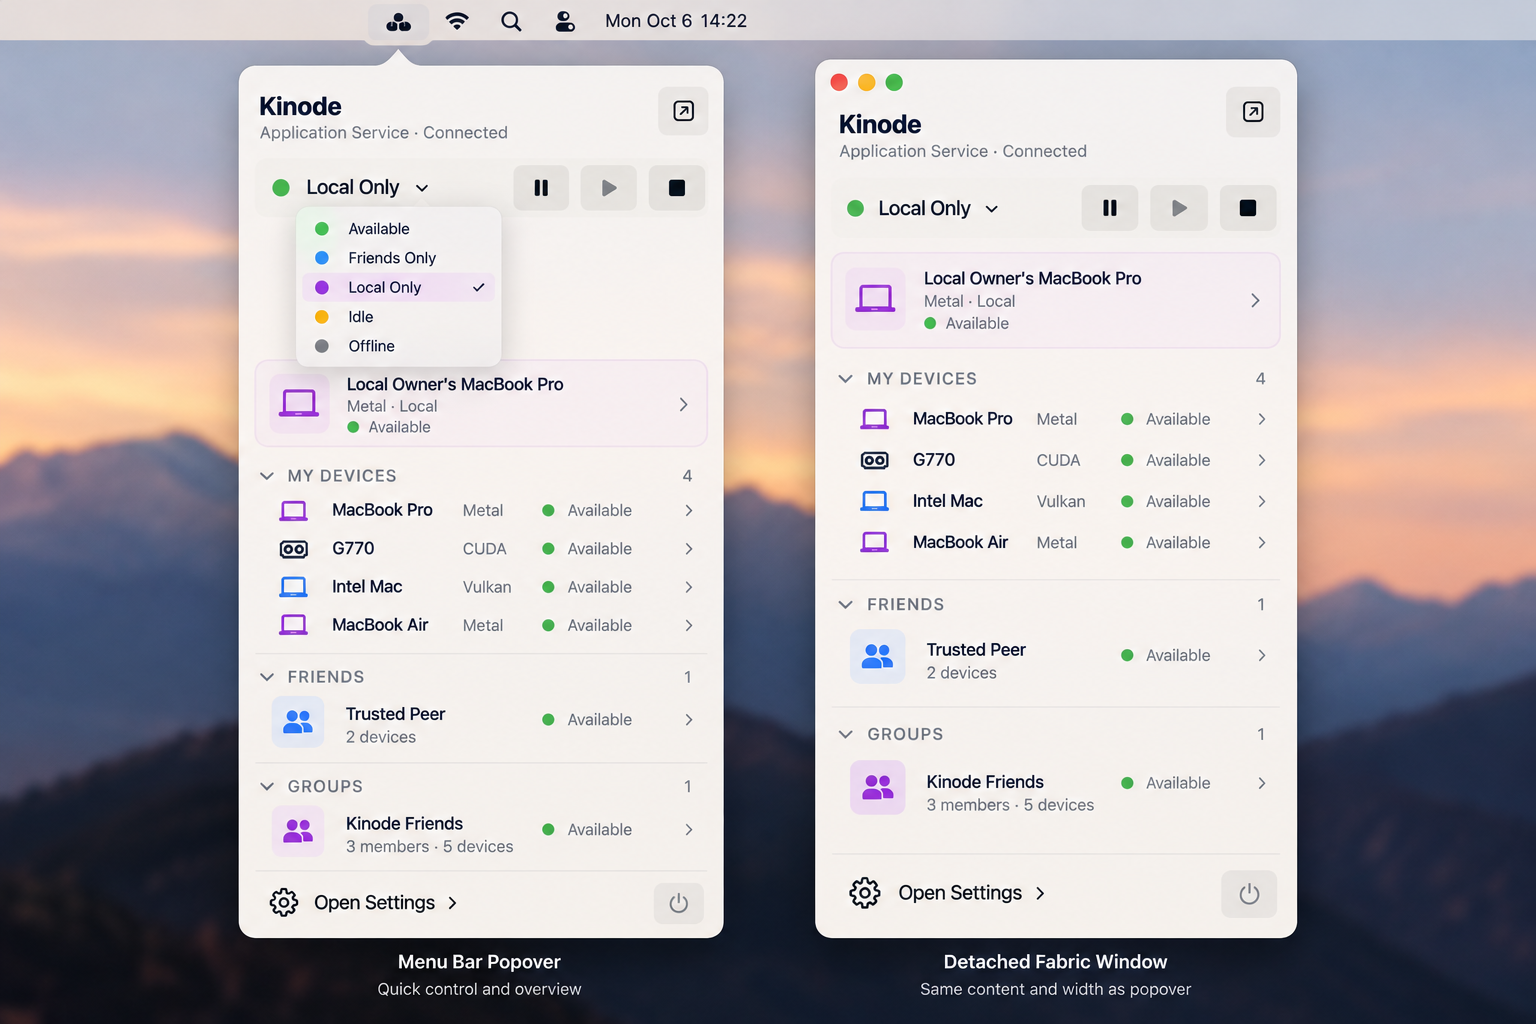
Models, readiness and owner controls, brought into one native experience. Supplied interface previews include illustrative data and planned surfaces; they are not live activity, customer evidence or measured results.
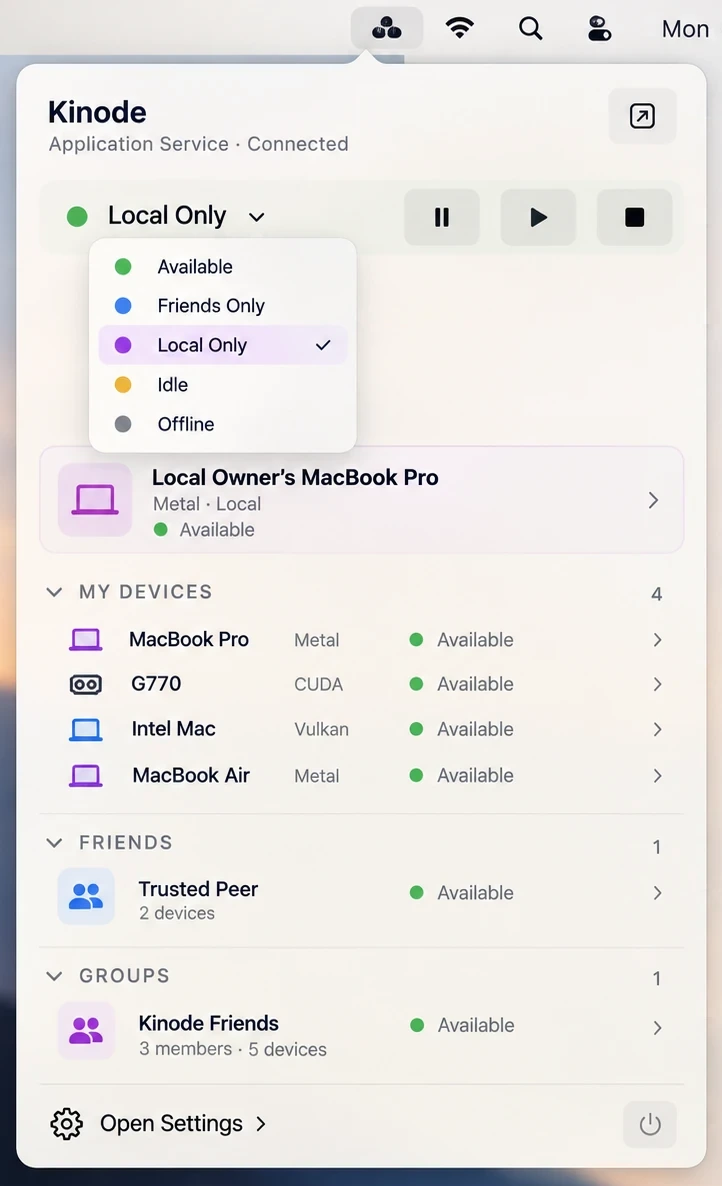
View the compact device-control preview
What’s next
A deliberate path forward.
- Demonstrated
Heterogeneous Execution
- In Progress
Oversized Capacity Unlock
- In Progress
Performance & Reliability
- Planned
Controlled Beta